Solo · 2025, re-evaluated Oct 2026 · live replay
Traffic signals with deep reinforcement learning
A PPO agent decides which direction gets green at a simulated four-way intersection in SUMO, and is compared fairly with fixed-time signal plans over five seeds.
What it shows
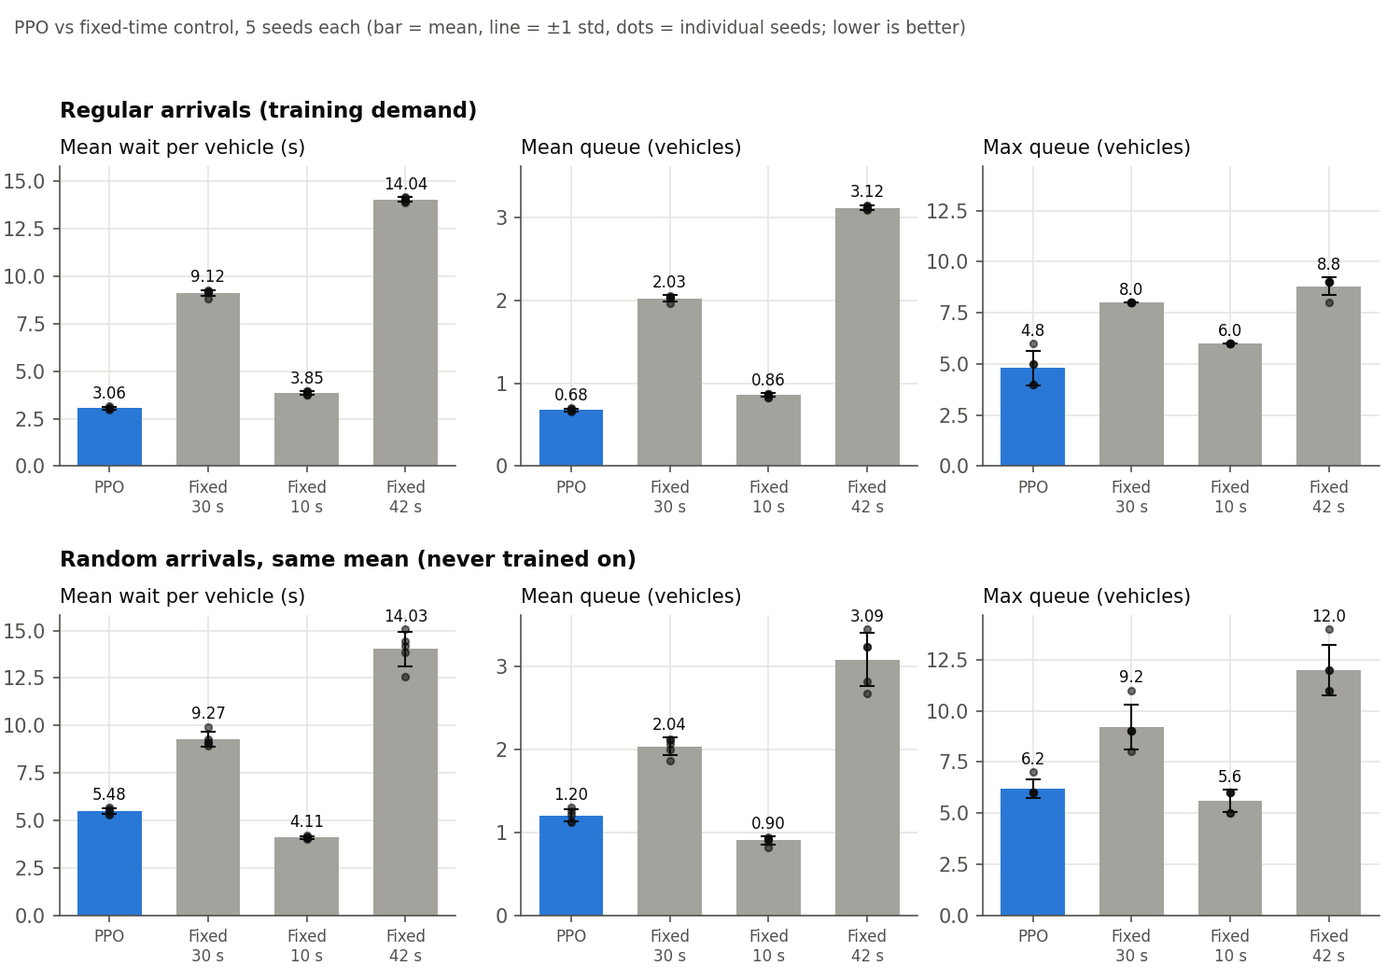
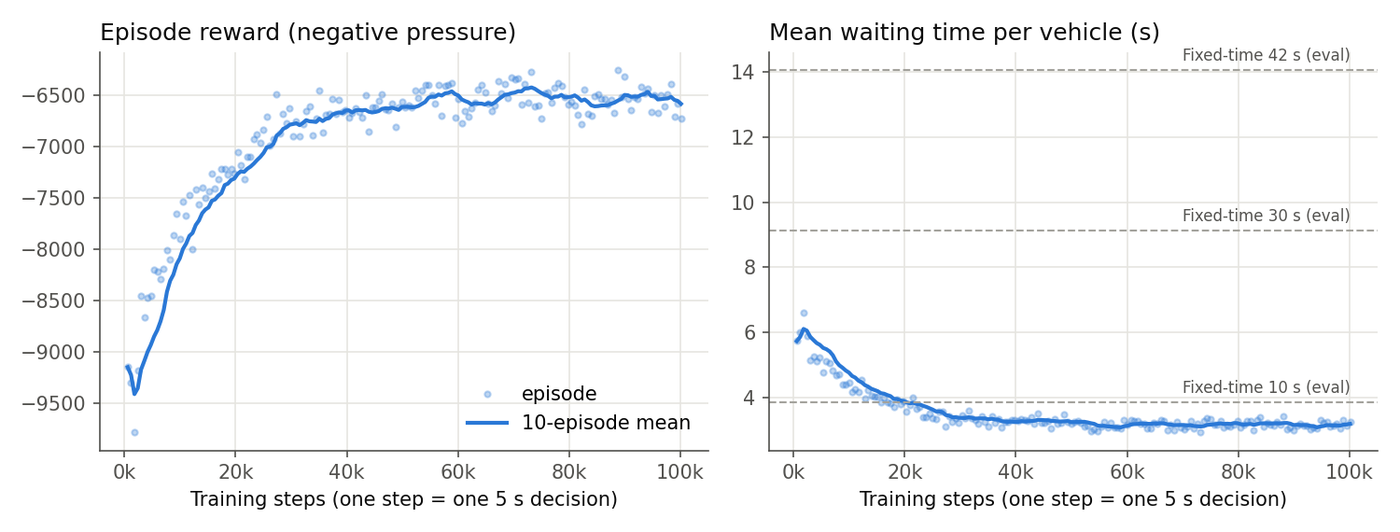
- Mean wait of 3.06s per vehicle vs 3.85s for the best of three fixed-time plans tested, on the traffic pattern it trained on.
- On random arrivals it never saw, it loses (5.48s vs 4.11s), and the write-up says so.
- Fixed an action-space bug that had the agent choosing between green and yellow instead of between directions.
- Python
- PyTorch
- Stable-Baselines3
- SUMO
- Gymnasium
Results
| Controller | Wait, trained pattern (s) | Wait, random arrivals (s) | Vehicles through (trained) |
|---|---|---|---|
| PPO | 3.06 ± 0.07 | 5.48 ± 0.16 | 792 |
| Fixed-time 30 s | 9.12 ± 0.16 | 9.27 ± 0.39 | 790 |
| Fixed-time 10 s | 3.85 ± 0.10 | 4.11 ± 0.07 | 792 |
| Fixed-time 42 s | 14.04 ± 0.12 | 14.03 ± 0.92 | 789 |
Mean ± standard deviation over seeds 1-5. Source: results/eval_summary.csv